This guide explains how Fleetgenius can help organizations plan routes, standardize workflows, and monitor fleet performance with an expert, operations-first view. Objectively, fleet-management platforms generally combine telematics, maintenance planning, driver coordination, and reporting to improve decision-making. The article also clarifies key purchasing considerations, supplier evaluation factors, and practical steps to implement effectively.
Fleet operations often fail not because tools lack capabilities, but because the implementation ignores real-world workflows. Fleetgenius is typically assessed as a fleet-management solution that can support route planning, operational oversight, maintenance coordination, and structured reporting—so managers can make decisions faster and with fewer gaps between “what should happen” and “what actually happens” on the road.
When you evaluate Fleetgenius, focus on how it integrates with day-to-day processes: how dispatch updates schedules, how maintenance tasks are triggered and assigned, how exceptions are handled, and how leadership reviews performance. A platform is only as useful as the consistency it brings to operations. If your dispatchers still rely on ad hoc calls, if technicians still maintain parallel spreadsheets, or if supervisors can’t easily trace why a change was made, then “feature coverage” won’t rescue the program.
This article provides an objective, industry-focused framework for understanding Fleetgenius in the broader context of fleet management software, along with conditions you should confirm during supplier discussions and deployment planning.
Fleet management software is commonly used to centralize information about vehicles, drivers, trips, maintenance history, and operational events. In many industries—delivery, field services, utilities, logistics, and public-sector transport—the software stack aims to reduce uncertainty: fewer missed service intervals, clearer accountability for tasks, and better visibility into where resources are deployed.
Very fleet systems rely on some combination of telematics (vehicle data collection), operational modules (dispatch and routing), workflow features (alerts, approvals, tasking), and analytics (dashboards and reporting). From an operations perspective, the critical question is how reliably the platform turns raw data into usable actions for managers, supervisors, and drivers.
“Good” in practice typically means the platform behaves like an operational nervous system. It senses events (e.g., a vehicle deviates from a plan, a mileage threshold is reached, a driver’s status changes), interprets those events according to business rules (e.g., maintenance should be scheduled, dispatch should re-route, supervisors should approve an exception), and then drives execution (e.g., tasks created and assigned, schedules updated, records updated for auditability).
When evaluating Fleetgenius—or any fleet system—try to avoid thinking of it as a static database or a set of screens. Instead, treat it as a workflow engine with data capture and reporting layers. The “quality” of the system is measured by operational reliability: does it consistently create the right tasks, does it prevent contradictory instructions, does it help teams recover when something goes wrong, and does it preserve history so performance and compliance can be reviewed later?
Organizations usually compare multiple providers before choosing one system. Fleetgenius is generally discussed in the category of fleet optimization and fleet operations management, where operational visibility and planning disciplines matter as much as data capture.
To keep comparisons meaningful, avoid “feature-by-feature” judgments alone. Instead, assess outcomes like reduced response time for incidents, improved scheduling accuracy for service work, and stronger auditability of maintenance and compliance-related records.
It’s also important to recognize that fleet programs are not uniform. The same organization may want one set of workflows for a city-based delivery fleet and a different set for a long-haul operation. Even within a single organization, there can be differences across depots or service lines. A tool that appears to match requirements in a demo might not match reality if its workflows are harder to adjust, if it assumes a dispatch structure that differs from yours, or if it can’t accommodate exception patterns that are common in your operation.
Therefore, a practical evaluation strategy is to compare tools based on operational fit and implementation effort. Two systems with similar “capabilities” can diverge dramatically in: time-to-configure, quality of workflow governance, ease of integrating with existing systems, and how well they handle missing or delayed data. These are the areas where many deployments succeed or fail.
You mentioned price information and supplier details, but no concrete figures or named suppliers were provided in the request. Because pricing is highly dependent on fleet size, integration scope, telematics coverage, number of users, and service-level expectations, the very responsible approach is to request a structured quote and confirm assumptions in writing.
Below is an expert purchasing checklist you can use with any fleet-management supplier, including those offering Fleetgenius.
From an industry standpoint, pricing should be evaluated against the “time-to-operational-value” you can realistically achieve—how quickly the platform can standardize workflows and reduce operational friction. A lower subscription fee is not a win if implementation drags on for months, data readiness is uncertain, or training is insufficient for dispatch and technicians.
When discussing Fleetgenius pricing, also request “option pricing” for likely growth. For example: additional depots, extra telematics sources, new driver onboarding flows, expanded maintenance scope, and deeper integrations with accounting or HR systems. This prevents the common situation where a company buys a core license but then pays disproportionate costs to expand beyond the initial rollout.
Your request includes a placeholder rule for locations: whenever a city/country appears in keywords, replace it with “nearby.” As no explicit location keyword was provided, this article keeps the localization concept at an operational level: fleet operations often vary by region due to road conditions, delivery density, typical service call patterns, and administrative requirements.
If you are deploying Fleetgenius or any comparable system “nearby,” treat localization as part of setup rather than an afterthought. Examples of practical localization include:
Localization is also about regulatory and administrative patterns that affect workflow. For instance, documentation expectations for compliance may vary by region. The way incidents are reported—what fields are mandatory, how quickly updates are expected, what approvals are required—can differ. Even if Fleetgenius provides generic templates, you should verify that local compliance fields and local operational terms can be configured without excessive customization work.
Finally, consider data lag and communications realities. In some “nearby” environments, coverage may be inconsistent, or telematics signals may arrive late. A good workflow engine anticipates delayed or missing data and still helps teams do their jobs. If the system assumes data always arrives instantly, dispatch and maintenance may be forced into manual fallbacks, reducing adoption and undermining the benefit of digitization.
Before committing, insist on clarity around deployment prerequisites. These questions reduce risk—especially if you operate across multiple depots or have legacy systems.
Additional requirements that often get overlooked include: user provisioning and deprovisioning (especially in organizations with frequent driver role changes), handling of temporary vehicle substitutions, and the process for updating service intervals when vehicle usage patterns change.
Also confirm how Fleetgenius handles “auditability by design.” In many fleets, audit requirements are not a separate feature—they depend on how the system records changes. You want traceability: who changed a schedule, who approved a maintenance extension, what data triggered a task, and what evidence was used. If those details are not captured, reporting may become less credible during internal audits or compliance reviews.
Across fleet organizations, the very durable results usually come from operational discipline:
Fleetgenius, in that sense, should be treated as an operational system. The value emerges when leadership uses it to enforce consistency and when supervisors use it to reduce time spent chasing information.
It’s also worth recognizing that adoption is not simply training. Adoption includes aligning incentives and accountability. If dispatchers are still evaluated on metrics that don’t match the new workflow structure, they may resist using the system fully. Likewise, technicians may avoid documenting tasks if the system adds work without clear benefits (e.g., less time searching for maintenance history, faster parts ordering, or fewer repeated approvals).
Therefore, when you evaluate Fleetgenius, ask how the system supports day-to-day accountability. For example: Does it make it easy to see what work is due? Does it enforce approvals for certain actions? Does it provide an operational timeline for each vehicle and each job? These are the practical elements that shape whether the software becomes “the way we work” rather than “the tool we look at sometimes.”
Even if you ultimately choose Fleetgenius, the deployment plan is often similar across reputable fleet-management vendors. Below is a structured guide you can adapt.
A key factor that often determines success is “change management” during the pilot. If your pilot team uses the system but the rest of the organization continues the old workflow, you risk inconsistent handoffs and false conclusions about system readiness. Therefore, even in a pilot, you should align key operational stakeholders so that the pilot is meaningful.
Another practical recommendation is to establish “workflow ownership.” Assign a named person or small team who owns the configuration rules and is accountable for keeping workflows aligned as the organization changes. Without that ownership, the system can drift into undocumented customizations, and upgrades later become painful.
The table below is designed as a practical comparison framework. It is intentionally generic (no links, no claims about unverified pricing) so you can apply it when requesting quotes for Fleetgenius or competing systems.
| Evaluation area | What to look for | Questions to ask the supplier | How to judge readiness |
|---|---|---|---|
| Workflow fit | Whether modules match dispatch, maintenance, and oversight processes | Which workflows are configurable? Can we mirror our approval steps? | Pilot supports your top use-cases without major workarounds |
| Data requirements | Compatibility with existing telematics, identifiers, and records | What data fields are mandatory? What happens if data is missing? | Clear data mapping plan with validation steps |
| Reporting and auditability | Ability to produce decision-ready reports and historical logs | Can we export records for audits? Are reports customizable? | Reports reflect real operational questions, not just generic KPIs |
| Integration scope | Connections to ERP, HR, maintenance management, or work order tools | Do you provide API documentation? What is integration effort? | Integration is defined with timelines and owners |
| User adoption | Training, role design, and usability for dispatchers and technicians | What training resources and materials are included? | Users complete scenario-based exercises successfully |
| Support model | Escalation paths and response times for incidents | What are support hours? How are urgent issues handled? | Documented SLA and clear escalation contacts |
| Total cost of ownership (TCO) | Platform fees, data/device costs, implementation labor, and ongoing maintenance | What costs exist beyond subscriptions? Any onboarding fees? | TCO includes onboarding, integrations, and realistic staff time |
To make the table more actionable during vendor interviews, use a scoring mechanism. For each evaluation area, rate (a) capability fit, (b) configurability effort, and (c) operational risk if assumptions are wrong. Then, compare vendors based on the combined score rather than a single dimension. This prevents “checkbox wins” from misleading you.
Also, request proof of operational behavior, not just feature descriptions. For workflow fit, ask to see how the tool handles a realistic exception: e.g., a delayed job triggers maintenance work, requiring approval, then rescheduling. Watch for whether the workflow is traceable and whether the system produces consistent records.
Fleetgenius is commonly positioned for managing day-to-day fleet operations—helping teams coordinate vehicle activity, maintenance planning, operational oversight, and structured reporting. The exact scope depends on the modules and integrations enabled during setup. In most deployments, the tool becomes most valuable when it links operational events to follow-up actions (maintenance tasks, route adjustments, approvals, and record updates).
Use your local workflow reality as the benchmark: depot-to-customer routing patterns, maintenance scheduling style, supervisor review cadence, and exception handling. Run a pilot that reflects these operational conditions rather than a generic demo scenario. A particularly useful approach is to select two or three “local realities” that are unique to your operation (e.g., frequent rescheduling due to customer windows, specific contractor workflows, or local road constraints) and test whether Fleetgenius can model them cleanly.
Also evaluate the “human factors” of local operations. Are drivers expected to interact with the system through a mobile interface? If so, test usability in conditions that resemble your operations (shift length, connectivity variability, language requirements). A system that looks good on a webinar can fail in real driver workflows.
Collect fleet size (vehicles and drivers), locations/depots, device/telematics status, expected integrations, required reporting outputs, and the number of user roles. Provide the supplier with target workflows so the quote reflects implementation scope, not just software access. To improve quote accuracy, also provide an estimate of how many work orders you create per month and how maintenance tasks are typically structured (e.g., preventive vs. corrective, internal workshop vs. external contractors).
In addition, prepare information about data migration complexity. If you have years of maintenance history in inconsistent formats, it may affect implementation time and cost. Clarify which historical data is necessary at launch vs. which can be imported later or approximated.
Many fleet platforms offer integration options, but the feasibility varies by your current tools and data formats. Ask for a documented integration approach (API/file-based/integration middleware), a list of supported data objects, and a realistic timeline for each connection. Integration feasibility should be assessed not only from the supplier’s side, but also from your data governance side: ownership of master data, mapping complexity, and who approves the field definitions.
Also ask how integrations are monitored. If integrations fail silently, you may only discover issues when dispatch schedules are wrong or maintenance tasks are missing. Reliable integration includes monitoring, alerts, and a defined recovery process.
Implementation timelines vary based on onboarding complexity, data migration needs, and integration effort. The very reliable method is to negotiate a phased plan (pilot first) with milestones tied to configuration completion and acceptance criteria. Ask for a timeline that includes internal tasks on your side (e.g., data cleanup, process sign-offs, training scheduling) so the plan reflects reality.
Implementation is sometimes slowed by unclear decisions rather than technical issues. For example, if approval steps are not agreed upon, the configuration can’t be finalized. That’s why workflow design and governance should begin early.
Track operational metrics aligned to your goals: service work order cycle time, adherence to maintenance schedules, time spent resolving operational exceptions, and dispatch accuracy (e.g., updates made within target windows). Consider also measuring workload distribution: are dispatchers spending less time manually searching for information? Do technicians spend less time locating prior maintenance history? These indirect measures often reflect real adoption.
Additionally, measure data reliability: the rate of missing fields, the timeliness of telematics updates, and the frequency of integration errors. A pilot that shows “successful screens” but poor data reliability can still fail at scale.
Common blockers include incomplete master data, unclear maintenance approval steps, insufficient training for dispatch and technicians, and lack of governance for workflow changes. Adoption improves when responsibilities are defined and scenarios are practiced. A frequent cause of stall is “partial usage” where some teams use the tool while others continue their old processes. That creates duplicate records and confusion about which system is authoritative.
Another stall cause is missing leadership feedback loops. If supervisors don’t regularly review system outputs and coach teams based on the metrics, users may feel the system is not improving their work. Adoption is sustained when the organization uses the data to make decisions that matter.
Fleet operations often require recordkeeping for maintenance history, operational events, and driver assignments. Confirm whether Fleetgenius can store audit-relevant history and support role-based access and exportable records. For compliance readiness, you should also confirm retention policies (how long data is stored), export accessibility, and whether logs include changes made to critical workflows.
If you operate in regulated contexts, ask whether Fleetgenius supports separation of duties. For instance, can dispatch create tasks while technicians approve completion, with managers reviewing exceptions? Separation of duties is often part of audit readiness.
While this article focuses on practical evaluation guidance, it is helpful to ground expectations in broadly documented industry themes—namely, that telematics-enabled visibility and structured maintenance practices can improve operational decision-making. For general research context on telematics and fleet management impacts, consult reputable industry and standards sources such as:
Note: The article avoids quoting specific performance numbers for Fleetgenius because those outcomes depend heavily on configuration, data quality, fleet composition, and operational maturity. If a supplier provides quantified claims, request the methodology, study scope, and comparability conditions. In procurement, a number without a comparable context should be treated as marketing until validated through references or through your own pilot measurement plan.
Also, consider that technology outcomes often depend on organizational factors: adherence to preventive maintenance, training quality, and the discipline of updating the system when events occur. Telemetry can be accurate, but it does not automatically produce better decisions unless the workflow transforms telemetry into actions and governance into accountability.
Fleetgenius can be a strong candidate when your organization needs more than dashboards—when you need consistent workflows, reliable event handling, and reporting that supports action. Use a rigorous evaluation approach: confirm requirements, validate integrations, pilot with representative operations, and measure outcomes that matter to your team.
In fleet management, software does not replace operational discipline; it amplifies it. The top results come from aligning the system to real responsibilities—dispatchers, technicians, managers—and ensuring the platform is configured to support how work actually flows, including in “nearby” operational environments.
To close the loop, remember that evaluation is not a one-time decision. Even after selecting Fleetgenius, continuous improvement matters. Fleet workflows evolve as staffing changes, new vehicle categories are added, and customer expectations shift. Treat Fleetgenius as a living operational system: establish governance, keep master data clean, iterate workflows based on pilot findings, and maintain a cadence of review so the platform keeps matching the real way your fleet operates.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
4rkojvsx Technology: Industry Insights and Buying Guide
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You

Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
Unveiling RS Sul Telecom Services
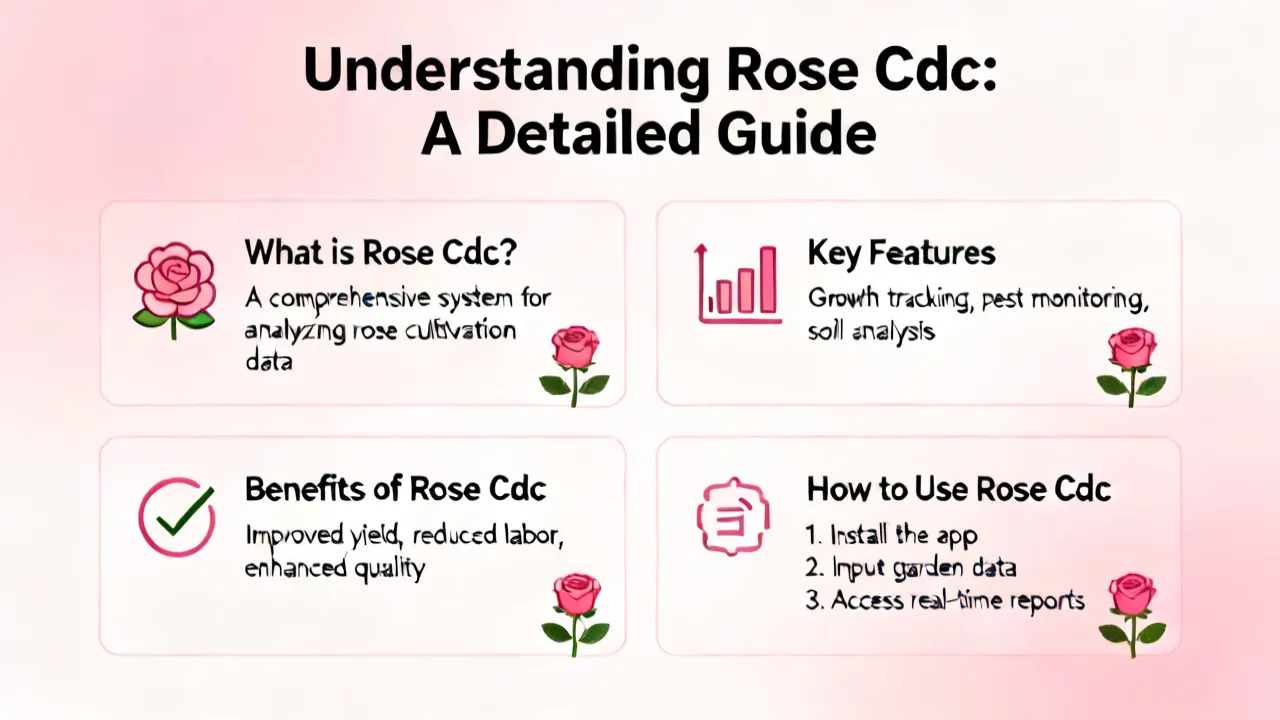
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.