Fleetgenius helps fleet managers organize data, improve operational visibility, and support more consistent decision-making across vehicles, drivers, and maintenance workflows. This guide explains what “Fleetgenius” typically represents in fleet technology, the kinds of capabilities fleet teams compare, and how to evaluate vendors objectively for fit, implementation effort, and good operational value.
Fleetgenius is often discussed as a fleet-technology solution designed to bring together the moving parts of fleet operations—vehicle records, maintenance planning, driver and usage information, and operational reporting—so managers can make steadier, better-informed decisions. Rather than treating fleet management as a collection of disconnected spreadsheets, teams evaluate platforms like Fleetgenius to standardize workflows and improve visibility across daily operations.
In practice, buyers typically want three outcomes: (1) fewer “unknowns” in day-to-day fleet performance, (2) more predictable maintenance and compliance routines, and (3) reporting that supports planning rather than simply documenting what already happened. The sections below provide an expert, vendor-neutral framework for assessing Fleetgenius and similar fleet operations tools, including how to think about cost, supplier relationships, and deployment requirements.
Throughout, the goal is to keep the evaluation grounded in operational reality. Fleet systems succeed or fail based on how consistently information flows through them—how work orders get created, how maintenance schedules are updated, and how teams handle exceptions. A useful platform is not just a data repository; it is a decision-support and workflow-support system that aligns responsibilities across dispatch, maintenance, administration, and management.
While product capabilities can vary by vendor and edition, Fleetgenius-style platforms generally aim to consolidate fleet data and operational tasks. Fleet managers commonly look for support across the following functional areas:
From an industry-expert perspective, the key is not merely “having features,” but ensuring the workflow matches how fleet teams operate: who updates what, when exceptions occur, and how actions get documented. A platform that stores data without enabling practical workflows can still leave managers with fragmented operational reality.
To make this more concrete, consider the difference between a database and an operational system. A database can hold a vehicle record. An operational system ensures that when a vehicle is reassigned, maintenance schedules follow the asset’s new utilization context, and historical documents remain linked. Similarly, reporting becomes actionable only when the underlying workflow reliably captures triggers—such as when mileage thresholds, engine-hour thresholds, or usage-based inspections require action.
Fleet managers often want the platform to support multiple maintenance approaches. Some fleets prioritize mileage-based preventive maintenance; others use time-based intervals or hybrid rules. Many fleets also incorporate compliance inspections (e.g., inspections for tires, brakes, safety checks, or regulatory-required documentation). The strongest systems allow rules to be configured so the operational logic reflects how the fleet is actually managed.
Fleet management is operationally sensitive. Small misalignments—such as maintenance schedules not tied to actual usage patterns, or reports that are too slow to inform dispatch—can create downstream cost and service impacts. Therefore, when teams consider Fleetgenius, they usually weigh operational fit more heavily than generic marketing claims.
Reliable evaluation also benefits from credible industry context. For example, the U.S. Environmental Protection Agency (EPA) and other authorities have documented that proper maintenance and tire management can affect fuel economy and emissions outcomes. While this does not “prove” performance improvements for a given vendor, it reinforces why structured maintenance planning is a meaningful operational objective. For reference, see the EPA’s materials on transportation and fuel economy and related maintenance considerations (EPA, U.S.).
When evaluating any fleet platform, it helps to ask: will this reduce uncertainty for the people who must make decisions under time pressure? Dispatchers need to know whether a vehicle is available and safe to deploy. Maintenance coordinators need to know what is due next and what is blocked by parts or vendor scheduling. Fleet managers need visibility into costs, downtime causes, and compliance status. Without operational alignment, software may produce “pretty reports” while failing to improve outcomes.
Operational thinking also influences how a team measures success during the pilot. Instead of evaluating solely by whether users can log in or whether data appears in dashboards, the team should define operational KPIs. Examples include:
With those KPIs in mind, the platform’s ability to support workflow ownership becomes the differentiator.
In fleet software buying, “price” rarely maps neatly to total cost of ownership. Even when a vendor shares price information, the final budget depends on adoption scope, number of vehicles/users, integration complexity, and implementation effort.
When evaluating Fleetgenius, ask for a transparent pricing breakdown that clearly distinguishes:
Expert condition: If Fleetgenius pricing is provided only as a single figure without scope definitions, request a written statement of what is included. This protects procurement decisions and reduces budget surprises during rollout.
Because fleet organizations often evolve over time—adding vehicles, changing contractor models, or expanding into new regions—the “expansion cost” should be treated as a first-class budget line item. A common procurement failure is to ignore how the license model scales when fleets grow. For example, if the pricing scales by active drivers rather than vehicles, adding new routes or gig drivers could unexpectedly inflate costs.
Beyond license and implementation, total cost of ownership includes operational time. Even if the software license seems reasonable, organizations should estimate the internal effort required to:
Therefore, a procurement team should ask the vendor not only “what is the cost,” but “what is the expected workload and responsibilities on both sides.” Vendors that provide clear responsibility matrices (e.g., RACI) typically reduce risk in real deployments.
Fleetgenius is only one part of the relationship. The supplier’s delivery capability can strongly influence the outcome. Objective due diligence typically covers:
From a practical standpoint, buyers should treat the supplier as a delivery partner. A well-designed fleet system can still underperform if the supplier cannot match your operational reality. For example, if your fleet has multiple maintenance tiers (in-house service, partner garages, roadside assistance vendors) the supplier should understand routing and work-order lifecycle requirements across those tiers.
To avoid misunderstandings, due diligence should also confirm:
These questions shift the conversation from “feature fit” to “delivery success.”
To evaluate Fleetgenius objectively, focus on “fit” criteria that affect day-to-day outcomes:
These questions help you separate “technology you can install” from “technology you can operationalize.”
Operational fit should also include “exception handling.” In fleet operations, exceptions are constant: a vehicle breaks down before a scheduled service, a driver changes schedules, a maintenance job is delayed due to parts availability, or compliance documents expire. A platform that handles the normal flow but not the exception flow can create hidden operational friction.
Therefore, during demos or workshops, you should request scenarios that involve exceptions. Examples include:
Asking these questions reveals whether the platform supports the messy realities that drive costs.
Even when no specific city or country is named, fleet deployments often behave differently “nearby” due to regulatory interpretations, contractor networks, and service schedules shaped by local conditions. For example, maintenance intervals, inspection routines, and service availability can vary depending on local supplier capabilities and typical vehicle usage patterns.
Accordingly, teams evaluating Fleetgenius should confirm whether the system supports operational variations “nearby,” such as:
This is often where implementation quality matters as much as software capability.
Localization is not only about language. It includes how the platform defines and enforces business rules that may differ across regions. For instance, some fleets require inspections at fixed calendar intervals, while others base compliance on vehicle usage. Similarly, document retention policies may vary based on local legal requirements or audit requirements.
To evaluate this properly, teams should ask for an example of a region-specific configuration. In practical terms, that might mean:
Even if the platform is global, the configuration and governance should support local operational nuance without creating “shadow processes” (spreadsheets outside the system) that defeat standardization goals.
Fleet improvements are frequently discussed in broad terms—fuel economy, reduced downtime, and smoother maintenance. While vendors may claim results, objective evaluation should rely on evidence and realistic expectations. For grounded reference points, buyers can consult:
Expert framing: treat software as an enabling system. Real-world outcomes depend on process discipline—how data is entered, whether work orders are acted on, and whether schedules are updated when operational reality changes.
It is also important to recognize that some outcomes are indirect. For example, better maintenance documentation may not immediately lower fuel cost, but it can improve audit readiness and reduce risk. Likewise, improved reporting may not instantly reduce downtime unless it leads to process changes—such as faster parts ordering or better scheduling.
Because of these indirect effects, fleets should plan for a “benefits realization” timeline. A structured approach often includes:
When fleets view the platform as part of a continuous improvement loop—not a one-time software deployment—expectations become more realistic and the organization is more likely to capture value.
A credible deployment for Fleetgenius typically follows a staged plan. Many fleet managers find that a pilot run reduces risk and clarifies what integrations and workflows need adjustment.
Critical condition: avoid launching with incomplete data definitions. If fields and responsibilities are not agreed upon, Fleetgenius or any comparable platform will “mirror” inconsistencies from the start.
To strengthen the implementation process, teams should also formalize governance and ownership early. Governance typically includes how changes are approved (e.g., when maintenance types or work order categories need to change), who can modify configurations, and how audit trails are maintained for changes.
A strong rollout plan also addresses adoption friction. For mechanics and coordinators, the biggest risk is increasing workload. If the new platform forces extra steps without reducing manual work elsewhere, adoption may stagnate. During the pilot, the organization should measure:
These pilot measures ensure the system improves operations rather than adding administrative burden.
Additionally, integration planning should be staged. For example, telematics data often arrives frequently and in a specific format, and it can be noisy or inconsistent. A robust implementation plan includes validation and error-handling. Teams should ask:
When these questions are addressed early, the platform can become a trusted source of operational truth rather than another data channel that users ignore.
The following comparison table helps structure evaluation work for Fleetgenius-style fleet management platforms. It is intended as a practical supplement, focusing on how organizations typically approach supplier validation, implementation steps, and conditions/requirements. (No links are included.)
| Evaluation Area | What to Collect (Source) | Step-by-Step Guide | Conditions / Requirements |
|---|---|---|---|
| Capabilities fit | Demo scripts, product documentation, workflow maps from your team |
1) List your top 10 operational decisions 2) Match each decision to a feature and workflow 3) Validate with a “day in the life” scenario |
System must support your approval logic and work-order flow, not just viewing data. |
| Pricing information clarity | Written quote, scope statement, edition details |
1) Request a breakdown by vehicles/users/modules 2) Confirm integration and onboarding inclusions 3) Compare total cost of ownership assumptions |
Quote should define included services, support level, and expansion terms. |
| Integration readiness | API/connectors inventory, telematics plan, data dictionaries |
1) Identify systems of record (ERP/HR/telematics) 2) Test data mapping with sample datasets 3) Define update frequency and ownership |
You need documented data formats and a tested migration strategy. |
| Data migration quality | Historical records sample, data audit results |
1) Profile existing data completeness 2) Define cleaning rules and required fields 3) Pilot migration and validate outcomes |
Migration must include validation checks and an error-approval process. |
| Security and compliance posture | Security questionnaire, audit logs description, retention policies |
1) Review access controls and roles 2) Validate encryption and audit logging details 3) Confirm data retention and export options |
Supplier must provide evidence-based security documentation appropriate to your environment. |
| Adoption and training | Training plan, user role definitions, change-management materials |
1) Identify key user groups (dispatch, maintenance, admin) 2) Run training with scenario-based tasks 3) Establish feedback cadence during pilot |
Training must be role-specific and tied to real workflows. |
To use this table effectively, teams should treat each evaluation area as a “proof point.” For example, capability fit cannot be validated by a generic demo alone. You should validate with scenario walkthroughs that match your internal terminology and approval thresholds. Likewise, integration readiness should be validated using test data mappings, not assumptions about compatibility.
Procurement teams can also use the table to create a formal evaluation scorecard. Many organizations fail by relying on qualitative impressions (“the demo looked good”). A scorecard improves consistency by requiring evidence for each criterion. Even a lightweight scoring model (e.g., meets/partially meets/does not meet) can help prevent bias and reduce decision churn later.
Even careful organizations can misjudge fit. Common pitfalls include:
These pitfalls are not unique to Fleetgenius; they are common across fleet platforms. The remedy is discipline: define responsibilities, validate workflows, and measure adoption during the pilot period.
To go deeper, here are additional pitfalls that frequently emerge after initial selection:
By anticipating these pitfalls, teams can reduce the risk that evaluation leads to a “systems mismatch” rather than a functional improvement.
A key step in evaluating Fleetgenius is turning requirements into workflow behavior. Requirements often start as vague goals (“better maintenance visibility”) and must be translated into operational steps (“when a work order is created, which fields are required, who approves, and how scheduling updates”). Without that translation, teams can end up with a system that looks good in demos but fails in real use.
Workflow mapping should cover not only happy paths but also the lifecycle of common events. Many fleets prioritize a set of “core workflows” that should work reliably:
During evaluation, ask the vendor to walk through these workflows using your fleet scenario: your vehicle types, your maintenance routines, and your approval processes. The goal is to verify that the platform can represent your operational logic without turning your team into “data entry administrators.”
Workflow mapping also helps you define the system’s “source of truth.” For instance, if telematics provides mileage updates, should those updates override manual odometer entries or only supplement them? If your ERP system tracks asset cost centers, should Fleetgenius reflect those cost centers as read-only or as editable fields? Source-of-truth decisions affect governance, reporting, and integration complexity.
Many fleet organizations underestimate data governance until after rollout. When governance is weak, dashboards become inconsistent, work order statuses become unreliable, and maintenance histories become incomplete. A structured evaluation should treat data governance as a core requirement.
Data governance typically covers master data and transactional data. Master data includes things like vehicle identifiers, maintenance types, work order categories, vendor names, locations, driver profiles, and compliance document categories. Transactional data includes work orders, events, inspections, odometer readings, service completions, and approvals.
Governance should define:
When evaluating Fleetgenius, you should ask how it supports governance. For example, can it enforce required fields per work order type? Can it restrict selections via dropdown lists or controlled vocabularies? Can it preserve audit trails for changes to critical fields?
Data governance also affects the migration phase. Historical data may be messy—missing fields, inconsistent units, and duplicate records. Governance and migration strategy should work together. The platform should support data validation and correction workflows, not just import data blindly.
In robust implementations, migration often includes profiling and cleaning steps, with rules for how to handle duplicates, how to map old maintenance categories to new ones, and how to interpret incomplete historical records. Without these steps, historical reports may become inaccurate and can reduce trust in the system.
Integration is often treated as a technical afterthought: “Can the system connect to telematics and our ERP?” In practice, reliability and governance are more important than connectivity alone. Telemetry data, for example, can be delayed, missing, or inconsistent. ERP updates can change over time. Document systems may require specific permissions and workflows.
A strong integration strategy includes:
During evaluation, request a documented approach to integration testing. Ask the vendor how they validate that odometer readings, maintenance events, or driver assignments remain consistent across systems. Also ask how they support ongoing changes (e.g., if telematics provider changes its data formats or if ERP fields evolve).
Because fleet operations often run continuously, integration downtime or failures can have operational consequences. A platform that integrates with good fallback mechanisms—like manual entry options with audit and validation—can maintain operations even when data feeds are temporarily disrupted.
Fleet platforms must be usable by people whose roles and daily tasks differ. A coordinator may spend most of the day creating and managing work orders. Mechanics may need quick access to job details and must be able to record service completion reliably. Dispatchers may need to confirm vehicle availability and compliance status before deployment.
User adoption evaluation should therefore focus on role-based experience. Questions to ask include:
A useful platform reduces “context switching.” For example, mechanics should not have to search multiple systems to verify the vehicle’s maintenance history or to confirm required documentation. Coordinators should not have to manually interpret unstructured notes; structured fields and controlled vocabularies help keep work orders consistent.
During pilot testing, measure not only system performance but also workflow friction. For example, if creating a work order requires many mandatory fields that are not always available at the moment of reporting, users will either delay reporting or enter placeholders, which damages data quality. The best systems allow incremental capture while still enforcing governance through validation and audit trails.
Role-based training also matters. A dispatch user should be trained on availability checks and scheduling implications, while a maintenance user should be trained on work order lifecycle, completion documentation, and compliance requirements. Training should not be generic or one-size-fits-all.
Reporting is often described as a key benefit, but reporting quality depends on how data is structured and how workflows feed into analytics. Fleet teams frequently say they want “visibility,” but the real need is decision support. Reporting should help answer practical questions like:
To evaluate Fleetgenius reporting capabilities, ask for example dashboards tied to operational goals. Also ask whether the platform provides:
One common pitfall is focusing on dashboards that show historical numbers but do not support proactive action. A more operational approach is to include “next action” reporting—what is due soon, what is overdue, what is blocked, and what requires approval. That requires the system to maintain accurate statuses and timestamps throughout the work order lifecycle.
When teams evaluate, they should test the reporting workflow with sample scenarios: “Show me all overdue preventive maintenance work orders for these locations,” “Show me vehicles with missing compliance documents,” “Show me work orders that took longer than the standard threshold.” The answers should be accurate and timely. If reporting depends on manual spreadsheet reconciliation, the system is not yet delivering decision support.
Fleet operations contain sensitive operational information. Depending on company requirements, it may include driver context, vehicle assignments, maintenance costs, vendor relationships, and compliance documentation. Therefore, security and auditability are not peripheral topics—they are prerequisites for trusted system operation.
When evaluating Fleetgenius, ask for evidence of:
Also ask how the platform supports multi-location organizations. For example, if a fleet spans multiple regions or depots, you may need to restrict visibility so that local teams can manage their assets while preventing accidental changes to other regions’ data.
Auditability is especially important for compliance and cost tracking. A platform should preserve evidence of when changes occurred and who made them. That becomes essential when auditors ask about maintenance schedules, compliance document updates, or the approval chain for exceptions.
Security questions should be paired with operational questions. For instance, if a user cannot edit certain fields due to role restrictions, what is the operational path? Does the system provide an approval or correction workflow, and does it preserve audit trails? If the correction path is unclear, teams may resort to workarounds outside the system.
Software adoption in fleet environments is deeply tied to organizational readiness. Change management should address how roles and responsibilities will evolve once Fleetgenius is deployed.
Before rollout, the organization should define:
A change management plan should also include communication. Users need to understand why the platform exists and how it affects their daily work. Without communication, adoption problems emerge not because users dislike the system, but because they are not sure what “good” looks like.
In mature programs, fleet leaders establish an adoption governance cadence, such as:
These governance rituals prevent the system from becoming a static deployment and instead keep it improving as real-world feedback is gathered.
Fleetgenius is commonly referenced as a fleet-operations technology approach that supports centralized fleet data, maintenance planning, operational visibility, and standardized workflows. Exact functions depend on the vendor’s edition and configuration.
Request a written quote that separates license scope, onboarding/implementation services, integration work, and support terms. Then compare total cost of ownership assumptions—especially costs tied to adding vehicles, users, or locations.
Procurement should request implementation methodology, data migration requirements, integration options (APIs/connectors), security posture documentation, and support SLAs. The goal is to reduce execution risk, not just buy software features.
Integration is often possible, but feasibility depends on available APIs/connectors, data formats, and integration ownership. The right step is to test with a sample dataset and confirm responsibilities for data updates and error handling.
Successful rollout typically requires: agreed workflows, defined data governance rules, role-based permissions, a validated migration plan, scenario-based training, and a pilot phase with feedback loops.
Software can enable improvement, but performance outcomes depend on operational discipline—accurate data entry, consistent work-order execution, and maintenance planning discipline aligned with usage realities.
Implementation timelines vary based on scope, data quality, integration complexity, and training needs. The top practice is to obtain a project plan with milestones (discovery, configuration, migration, pilot, rollout) tailored to your fleet footprint.
A pilot success plan should define operational KPIs, user roles and responsibilities, a workflow scenario list (including exceptions), data quality checkpoints, and a timeframe. It should also include a decision rule: whether to expand, adjust configuration, or refine data governance before full rollout.
Shadow systems often appear when the platform does not capture key workflow steps or reporting needs. Avoid this by prioritizing critical workflows first, configuring validation rules and required fields early, and ensuring reporting meets decision needs. During pilot, monitor whether users still maintain spreadsheets for the same steps and use that feedback to adjust configuration.
Work order statuses should reflect the actual lifecycle used by your team (e.g., open, scheduled, in progress, waiting for parts, completed, closed). Categories and maintenance types should use standardized vocabularies with controlled lists to maintain reporting consistency. Define required fields per status transition so reporting and analytics remain reliable.
Fleetgenius-focused evaluations work top when viewed as a change to how fleet decisions are made and documented. When buyers handle pricing information transparently, verify supplier delivery capability, and run a structured pilot, the platform is more likely to translate into daily operational consistency—maintenance reliability, improved visibility, and clearer reporting for management.
If your organization is planning a fleet management modernization “nearby,” consider starting with workflow mapping and data governance first. From there, Fleetgenius can be assessed as the system that supports those workflows—helping your fleet team move from reactive maintenance and fragmented reporting toward a more structured operations model.
Ultimately, the strongest fleet outcomes come from combining software capability with disciplined execution: clear ownership, consistent data standards, workflow coverage for exceptions, and reporting that drives proactive action. When those elements align, a platform like Fleetgenius becomes more than a tool—it becomes the operational backbone for fleet performance decisions.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
4rkojvsx Technology: Industry Insights and Buying Guide
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You

Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
Unveiling RS Sul Telecom Services
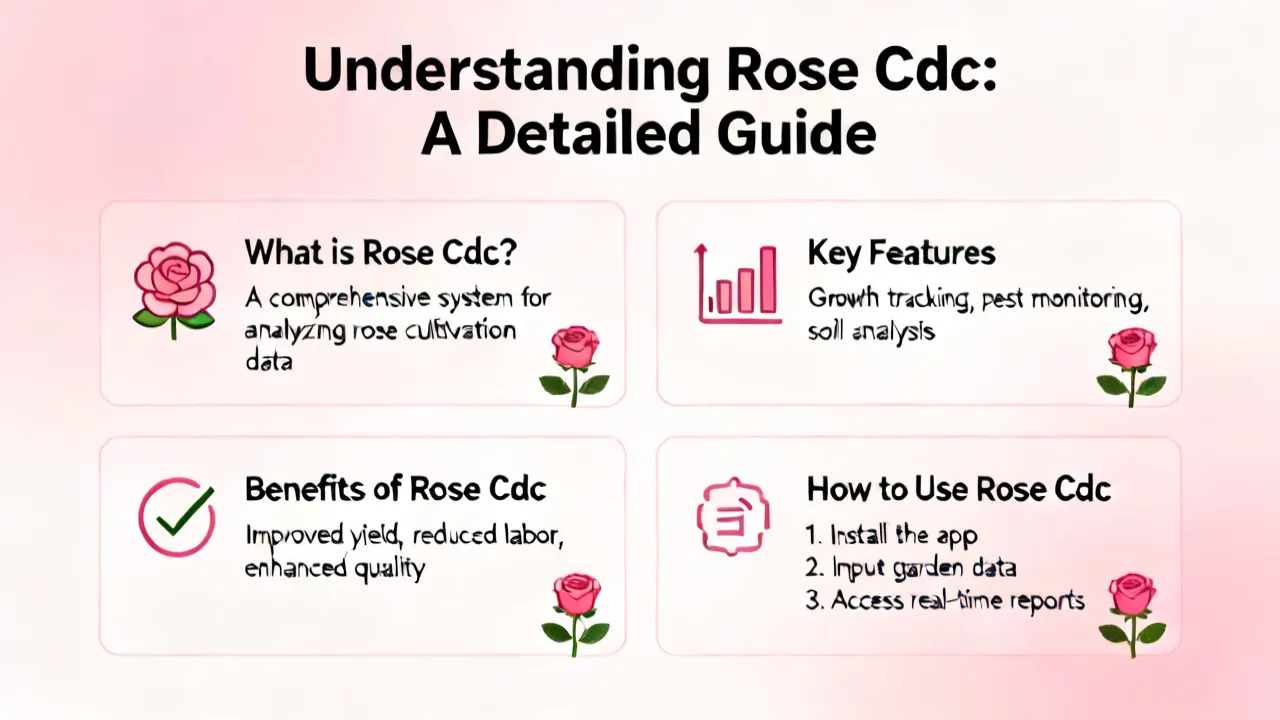
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.